TLDR
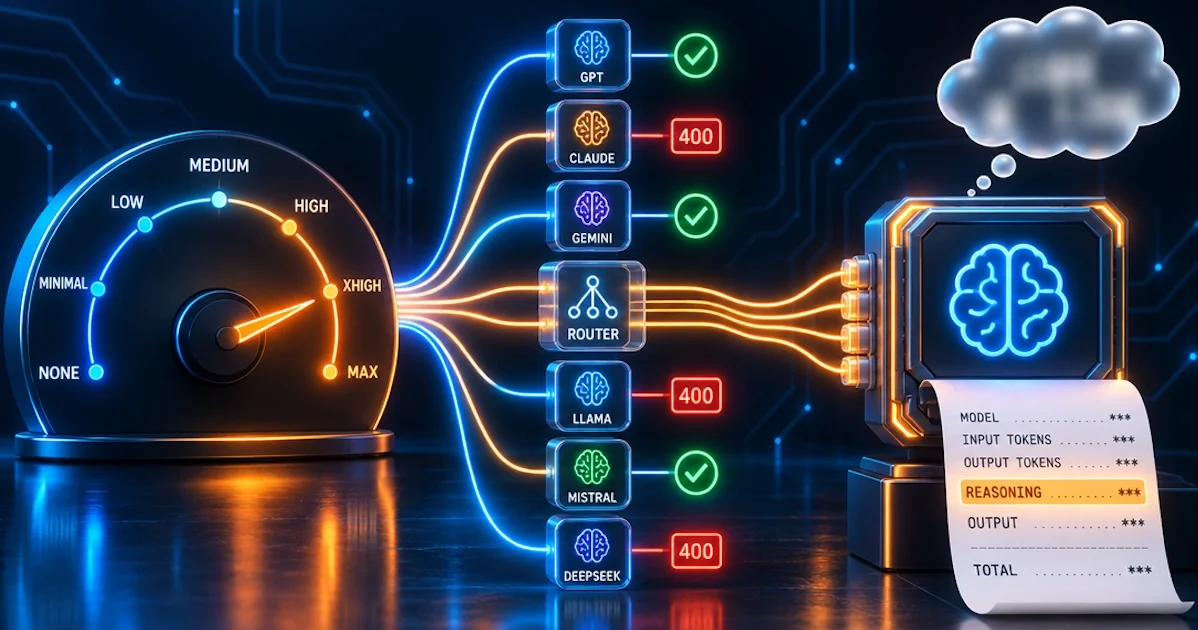
Every provider means something different by "reasoning effort". Of seven common values, the models accepted between two and seven; rejected values end with HTTP 400. Routers often accept everything — including values the provider behind them rejects. The thinking itself is always billed as output, even when you never get to see it. Part 2 of the series "What an LLM call really costs".
Introduction
Reasoning models "think" before they answer, and you can tell them how thoroughly. That sounds like a simple control: little thinking for easy questions, a lot for hard ones. In practice, the control has a different name at every provider, different levels, and it reacts differently to values it doesn't know.
For an application that talks to several providers, this is more than a question of style. A wrong value is a runtime error — or, worse, it's silently ignored.
1. The parameter zoo
| Provider | Parameter | Values according to the docs |
|---|---|---|
| OpenAI (Responses) | reasoning.effort |
none to max, differs by model |
| OpenAI (Chat Completions), xAI chat, routers | reasoning_effort |
differs by provider |
| Anthropic | output_config.effort |
low, medium, high, xhigh, max |
| Gemini 3 / 4 | thinkingLevel |
low, medium, high (more on some models) |
| Gemini 2.5 | thinkingBudget |
number of tokens, 0 = off |
| Open-weight models | enable_thinking, thinking, reasoning_effort |
differs by host |
Gemini rejects thinkingLevel and thinkingBudget in the same request. All three Claude models we tested answered Anthropic's old budget_tokens with HTTP 400.
2. What gets accepted
We sent a small reasoning task (the classic "bat and ball" question) to every model with each of the seven values. The table shows whether the value was accepted, followed by the reported reasoning tokens:
| Model | none | minimal | low | medium | high | xhigh | max |
|---|---|---|---|---|---|---|---|
| GPT-6.1 Sol | ✗ | ✗ | ✓ 11 | ✓ 14 | ✓ 13 | ✓ 34 | ✓ 68 |
| GPT-5.6 Luna (Responses) | ✓ 0 | ✗ | ✓ 0 | ✓ 17 | ✓ 23 | ✓ 23 | ✓ 45 |
| gpt-5-mini | ✗ | ✓ 0 | ✓ 64 | ✓ 128 | ✓ 320 | ✗ | ✗ |
| Claude Sonnet 5.5 | ✗ | ✗ | ✓ 0 | ✓ 0 | ✓ 0 | ✓ 0 | ✓ 107 |
| Claude Haiku 5.5 | ✗ | ✗ | ✓ 0 | ✓ 0 | ✓ 50 | ✓ 53 | ✓ 172 |
| Grok 4.7 | ✗ | ✓ 251 | ✓ 190 | ✓ 233 | ✓ 413 | ✓ 318 | ✗ |
| Gemini 3.8 Flash | ✗ | ✗ | ✓ 72 | ✓ 256 | ✓ 266 | ✗ | ✗ |
| Mistral Medium | ✓ 0 | ✗ | ✗ | ✗ | ✓ 306 | ✗ | ✗ |
| gpt-oss-120b at IONOS | ✗ | ✗ | ✓ 12 | ✓ 134 | ✓ 200 | ✗ | ✗ |
| Claude Sonnet 5 via Cortecs | ✓ 0 | ✓ 0 | ✓ 0 | ✓ 0 | ✓ 0 | ✓ 0 | ✓ 61 |
✓ accepted (reasoning tokens), ✗ HTTP 400. Single calls on 2026-10-19; token counts vary from call to call.
What stands out:
- OpenAI differs by model: GPT-6.1 Sol rejects
noneandminimal, gpt-5-mini rejectsxhighandmax. - Anthropic rejects
noneandminimaland is the only direct provider withmax. On Sonnet 5 and 5.5, our task produced not a single reasoning token up toxhigh; onlymaxmade the model think. At Claude, the effort is an upper limit, not an instruction. - xAI can't be switched off;
noneis rejected. - Gemini 3.8 Flash accepts only
low,mediumandhigh— and without a setting, it thinks as much as athigh. Gemini reports the thinking asthoughtsTokenCount. - Mistral accepted only
noneandhigh. - IONOS rejected
highfor Qwen3.8-27B, but notxhigh. Logic seems to be optional at some hosts.
3. Routers accept everything
Cortecs accepted all seven values for Claude, including none and minimal, which Anthropic direct rejects. EU Router also accepted every value for Claude. What the router does with them stays invisible: Cortecs documents a translation into thinking budgets of 1,024 to 4,096 tokens, which you can't read from the responses (not measurable). Requesty reports no reasoning tokens at all for Claude.
A router that accepts every value prevents runtime errors. But it also prevents you from noticing when your value doesn't arrive. Via EU Router, gpt-oss-120b even thought less at high than at low in our single call.
4. Hidden thinking, billed in full
Reasoning tokens are billed as output — and output is the most expensive part of a call (five times the input price at Claude Sonnet 5). The thinking itself is rarely shown:
- OpenAI doesn't show reasoning tokens; gpt-5-mini billed 256 of them for an eight-character answer.
- Claude Haiku 5.5 billed 53 thinking tokens without showing a single one.
- So if you count only the visible answer, you'll underestimate costs systematically.
Tip: Read the reasoning fields from the usage block and log them separately. That's the only way to see whether a higher effort actually makes a call more expensive.
5. Effort and cache
A change of reasoning effort costs the prompt cache at OpenAI, xAI, Gemini, Claude Sonnet 5 and the open-weight models — only Claude Sonnet 5.5 and Haiku 5.5 keep it. Part 1 has the details. For your architecture, this means: set the effort per conversation, not per message.
6. How we solved it in .NET
Evanto.ChatClients has exactly one effort vocabulary — none, low, medium, high, xhigh, max — and translates it per provider. For Claude, none becomes low, because current models don't allow thinking to be switched off:
private static String? ToAnthropicEffort(ReasoningEffort effort) => effort switch
{
    ReasoningEffort.None      => "low",
    ReasoningEffort.Low       => "low",
    ReasoningEffort.Medium    => "medium",
    ReasoningEffort.High      => "high",
    ReasoningEffort.ExtraHigh => "xhigh",
    _                         => null
};
Source: ToAnthropicEffort (excerpt)
max exists only at Anthropic and is dropped for other providers, with a warning in the log. In CompanyWizard, the admin UI offers per model only the levels that the model catalogue knows for that model.
Lesson Learned: A green connection test tells you nothing about whether the provider accepts your effort — the test doesn't send one. So a rejected value shows up only in the first real chat, as HTTP 400 with the provider's message.
7. What we deliberately left open
- Quality: We measured what is accepted and billed, not whether the answers get better.
- Variation: Reasoning tokens vary from call to call; the table shows single calls.
- OpenRouter doesn't fully normalise the values: for Claude it accepted all seven, for gpt-oss-120b it rejected
none.
Conclusion: patterns you can reuse
- Maintain effort values per model, not per provider — even OpenAI isn't consistent.
- Catch rejected values: HTTP 400 with a message like "not supported" is a configuration error, not a network problem.
- Check router responses: accepted doesn't mean passed on.
- Log reasoning tokens separately, because they sit in the expensive output.
- Set the effort per conversation so you don't lose the cache.
All raw data and scripts: github.com/evanto-media-ag/llm-caching-reasoning-costs
The series
- Part 1: Prompt caching compared — what carries the cache and what breaks it
- Part 2: Reasoning effort compared — seven values, twelve interpretations
- Part 3: Cost transparency — formulas, field names, price sources
- Part 4: Routers compared — Cortecs, EU Router, Requesty, OpenRouter
References
- OpenAI: Reasoning
- Anthropic: Effort
- xAI: Reasoning
- Google: Gemini thinking
- Cortecs: Reasoning · Requesty: Reasoning
Want to know which reasoning effort pays off for your use case? Let's spend 30 minutes on your specific workflow — no obligation, no cost, with concrete next steps at the end. Book a 30-minute call
Note: Article created with AI assistance.